 Back
Cerebras Goes Public on Nasdaq: "Wafer-Scale Computing" Reshapes Computing Power Boundaries, Driving Evolution of Ultra-High-Density AI Computing Infrastructure
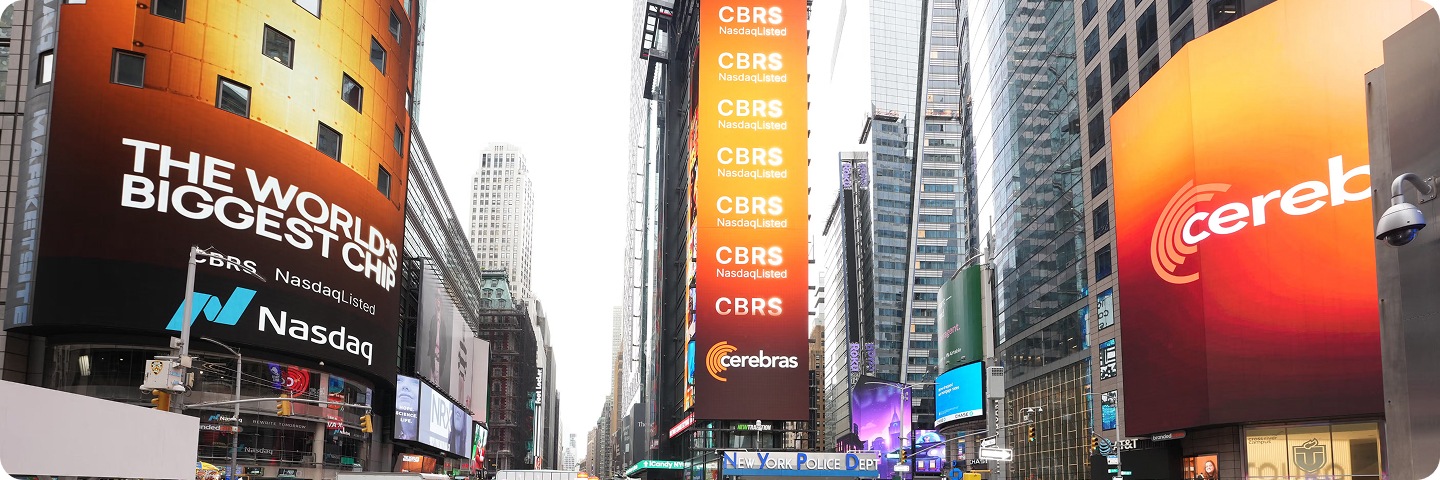
On May 14th, AI chip company Cerebras Systems officially went public on the US Nasdaq stock exchange. As a core driver of the "Wafer-Scale Computing" architecture, Cerebras' successful IPO marks that ultra-large-scale chip architectures have officially entered the large-scale commercial stage, opening a differentiated technological path for the evolution of global AI computing foundations. This milestone event not only reconstructs the competitive landscape of the existing AI accelerator market but also presents new requirements that break through current limits for the physical infrastructure and energy management of underlying data centers.
I. Breaking Through "Lithography Area" and "Memory Wall" Bottlenecks: Analyzing Cerebras' Microarchitecture Logic
In the current large model distributed training paradigm dominated by clustered GPUs, the horizontal scaling (scale-out) of computing power is often constrained by physical bandwidth bottlenecks and interconnection latency between nodes. Cerebras practices an extreme single-node vertical scaling (scale-up) philosophy, with its core product Wafer-Scale Engine (WSE) breaking through the physical area limits of the single exposure field (Reticle Limit) of lithography machines in the manufacturing process.
Taking the latest generation WSE-3 as an example, a single wafer-scale chip integrates approximately 4 trillion transistors and over 900,000 AI-dedicated computing cores. The core technical barrier of this architecture lies in the elimination of inter-chip and inter-node network interconnection losses and data transmission overhead from traditional distributed architectures at the physical underlying layer.
By relying on an extremely high-bandwidth 2D mesh interconnection network (2D Mesh) that tightly couples massive computing cores with up to 44GB of on-chip SRAM arrays on a single silicon die, Cerebras constructs a giant heterogeneous system with PB/s level internal interconnect bandwidth. This highly integrated memory-computing design ensures high-bandwidth throughput of model parameters and activations within the die, avoiding the "Memory Wall" and "Communication Wall" constraints faced by traditional clusters relying on external switching networks.
Additionally, at the software stack level, the entire wafer-scale computing unit is logically mapped to a single computing entity by the compiler. Developers do not need to intervene in complex distributed operator partitioning (such as tensor parallelism, pipeline parallelism), thereby releasing excellent linear scaling efficiency and computing power efficiency in training and inference of ultra-large parameter models.
II. Rise of Ultra-High-Density Computing Power: Modern AI Computing Center Physical Infrastructure Faces Generational Challenges
While the wafer-scale architecture achieves a leap in computing power density per unit area, it also completely reshapes the physical form factor and heat flux density distribution of traditional server rooms. Taking a single Cerebras CS series computing system as an example, its equivalent computing power thermal output is highly converged into an intensive single-node physical space from the original regular GPU cluster distributed across multiple cabinets.
This evolution of the underlying computing paradigm presents a cross-generational physical infrastructure test for currently deeply optimized modern AI computing centers (AIDC):
- Leap in per-cabinet power density: Currently, mainstream high-end GPU AI computing clusters are typically designed with per-cabinet power between 30kW and 50kW. However, cabinets with high-density deployment of wafer-scale computing systems directly leap to power densities of 100kW and even higher. This forces data centers to introduce highly customized high-voltage direct current (HVDC) or more advanced busbar power distribution architectures and to have extremely strict local power redundancy and dynamic allocation capabilities.
- Full-link liquid cooling transition to rigid standards: Facing the extreme heat flux density generated by a single ultra-large die, modern data-center-standard high-efficiency air cooling or air-liquid hybrid cooling systems can no longer effectively suppress concentrated chip hot spots. Wafer-scale systems must deeply rely on high-standard customized cold plate liquid cooling and other efficient cooling solutions, which present strict industrial-grade reconstruction requirements for data center pipe pressure standards, cooling liquid micro-circulation control, and temperature control precision of cold distribution units (CDU).
- Redefining machine room loading and spatial topology: The introduction of ultra-high-density systems changes the footprint model and floor load distribution of modern AI computer rooms. While significantly reducing the physical space for fiber optic cabling within the cluster, the load-bearing proportion and water system pipeline space requirements of underlying liquid cooling circulation facilities (such as cooling towers, water distributors, CDU pump groups, etc.) increase dramatically.
III. 3e Technology Strategic Insights: Forward-Looking Pre-Research for a Foundation Adapted to Future Computing Power Evolution
Cerebras' successful IPO has released a clear technological anchor point: Frontier AI computing hardware is evolving toward ultra-high integration and ultra-high power density. As a professional service provider deeply engaged in IT infrastructure and network architecture, 3e Technology (Nasdaq: MASK) is closely monitoring the profound mapping of this underlying hardware transformation on the macro data center ecosystem chain.
Facing the ultra-high-density computing power wave represented by "Wafer-Scale Computing," 3e Technology is conducting in-depth assessment from the perspectives of strategic pre-research and lifecycle planning, continuously tracking the engineering implementation of advanced liquid cooling architectures, 100kW+ ultra-high-power computer room designs, and new power distribution facilities.
In the new cycle of increasingly heterogeneous AI computing hardware, the company will uphold professional insights, deepen macro tracking of computing power evolution, and be committed to constructing sufficient elastic redundancy boundaries in future computer room site selection, spatial topology, and power usage effectiveness (PUE) design. Through steadily advancing the compatibility and iterative upgrades of underlying physical infrastructure, it will provide solid foundational support for the prosperous evolution of next-generation artificial general intelligence (AGI).